

Power BI template
To get started quickly, you can use a Power BI template file (.pbit) that includes all the utility functions and helper functions documented on this page. It also includes additional functions for incremental refresh. The template saves you from manually copying and pasting each function into your Power BI report.
Download Power BI template
Download the template file (
.pbit) to get started with all utility functions pre-configured.What’s included
The template contains the following components: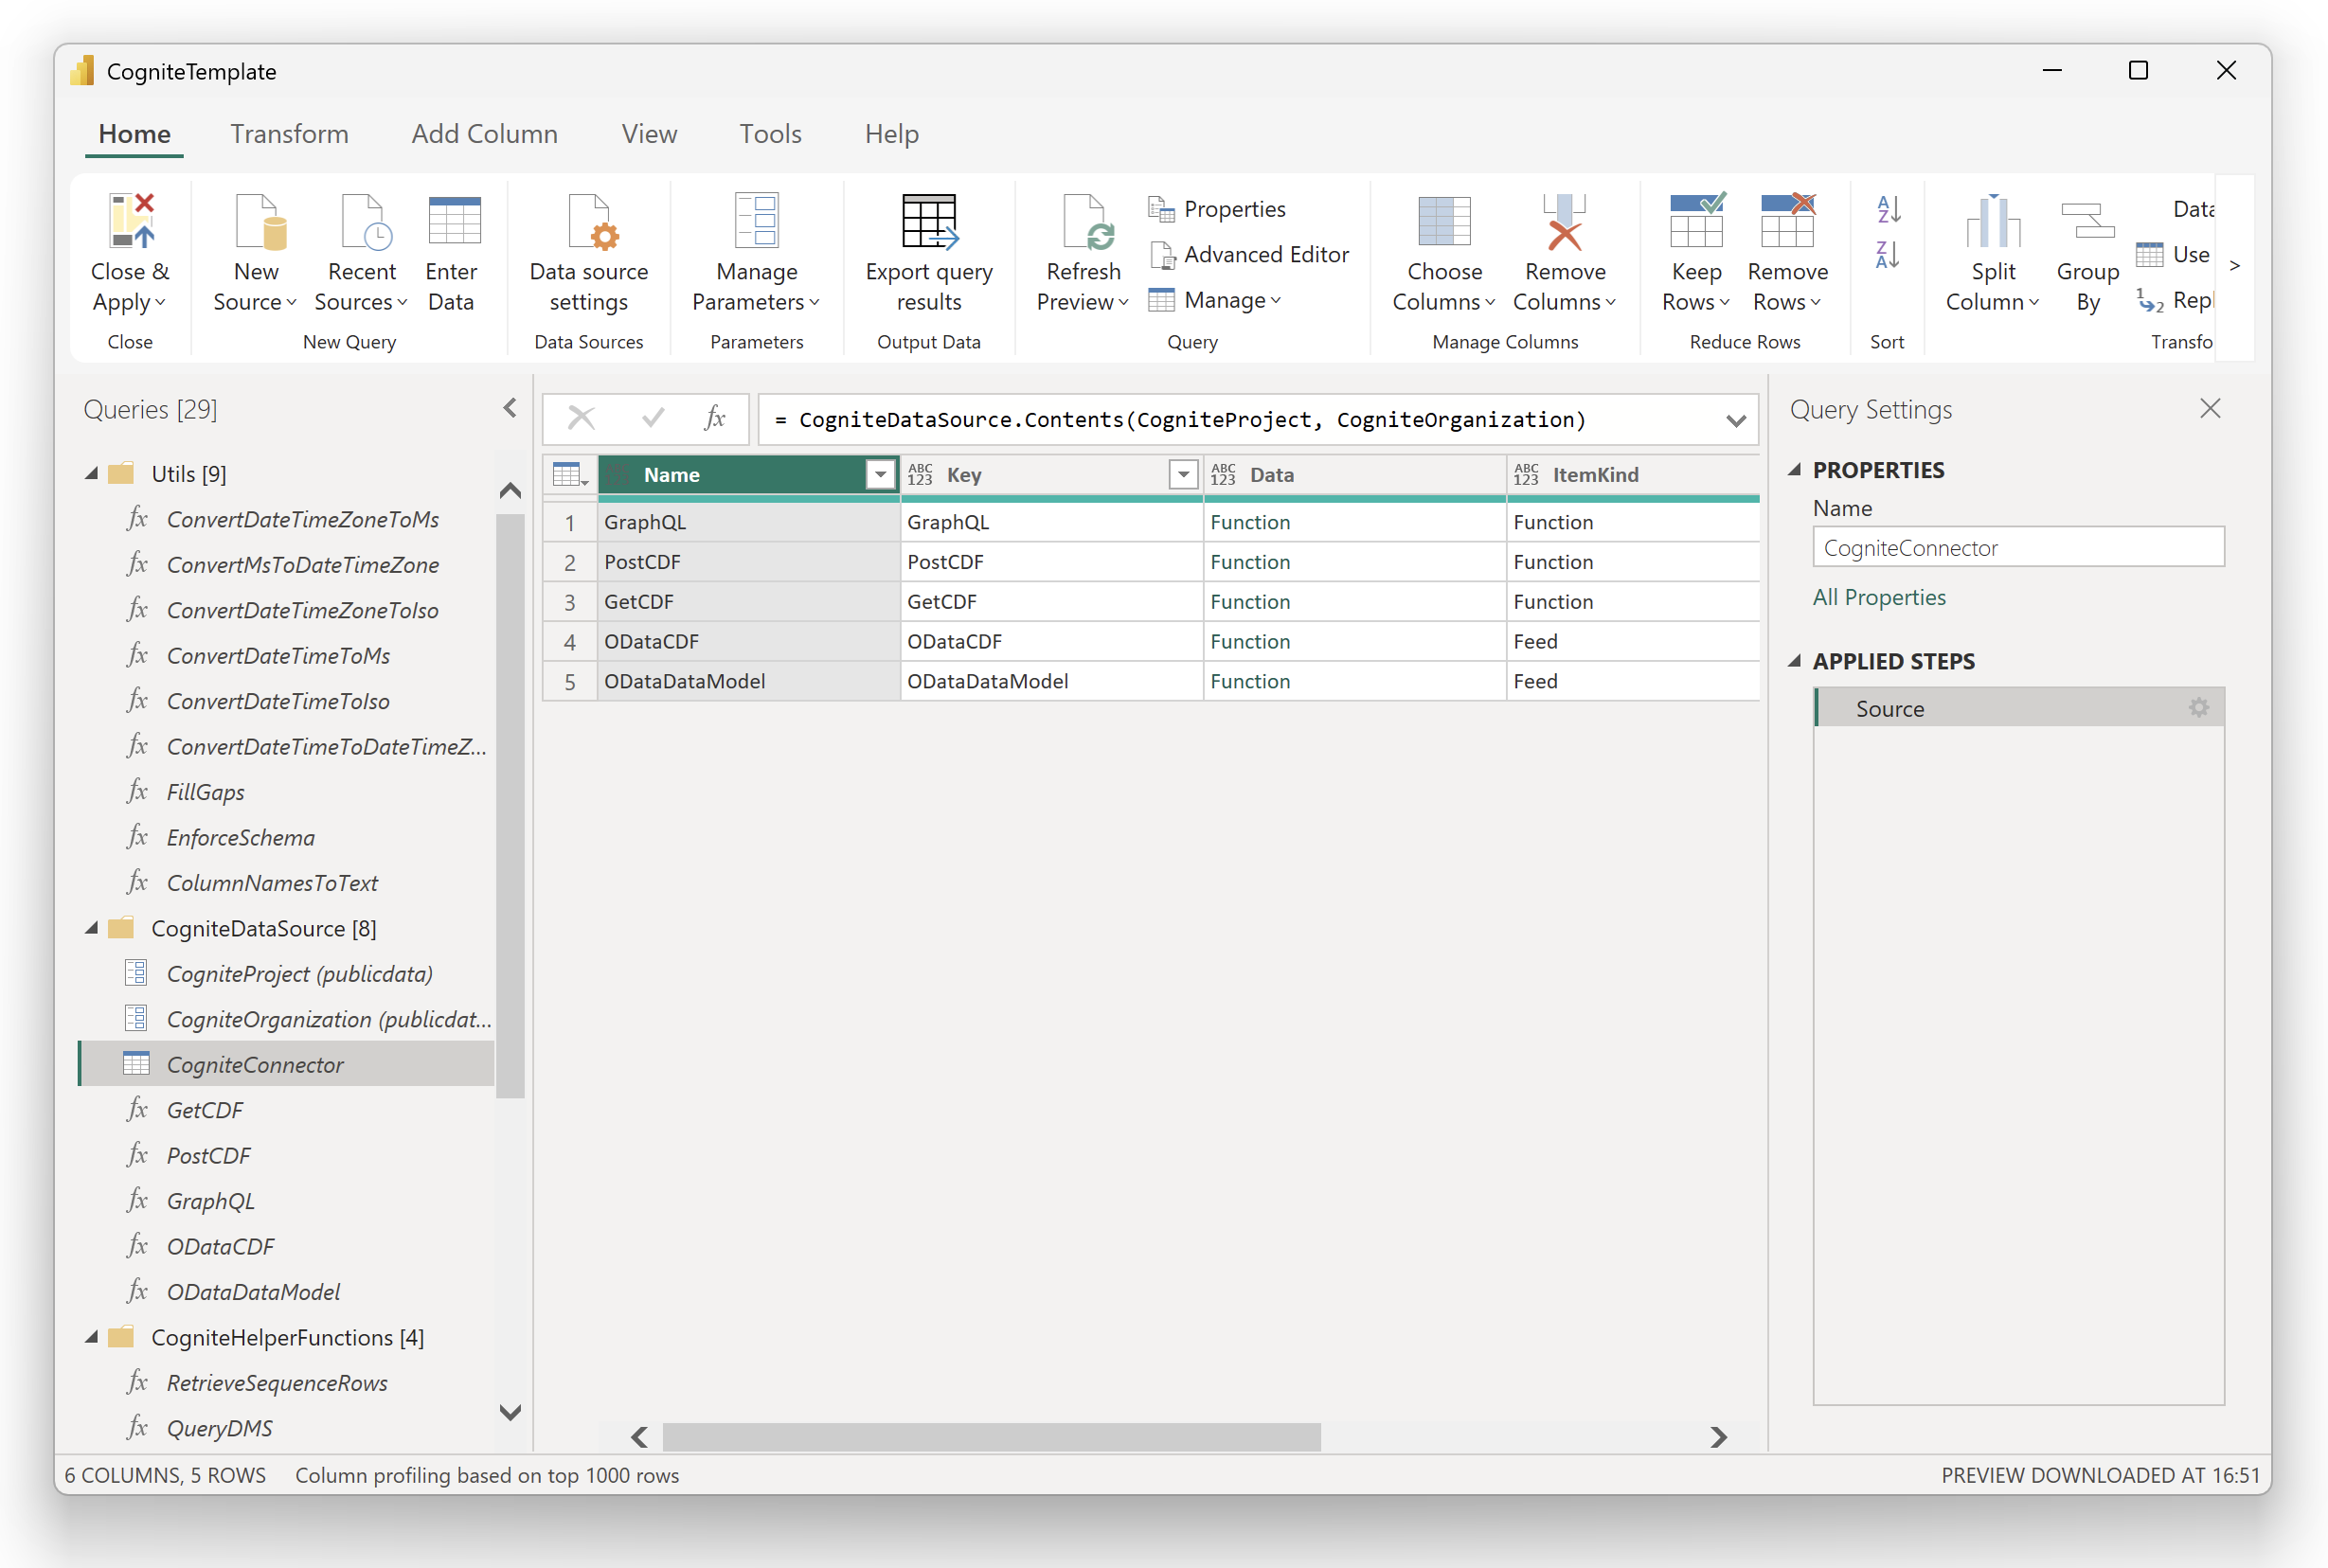
Getting started with the template
1
Download and open the template
Download the template file and open it in Power BI Desktop. Opening a template creates a new report and doesn’t modify the template file.
2
Enter connection parameters
When prompted, enter your CDF project name in
CogniteProject and your organization in CogniteOrganization. You can also set RangeStart and RangeEnd, or keep the default values. To change the values later, select Transform Data > Edit parameters.3
Sign in
When prompted, sign in with your organizational account to authenticate with CDF.
4
Start building
Select Transform Data to open the Power Query editor and view the functions. Create your queries using the pre-configured functions, or use them as a reference alongside the documentation on this page.
5
Save the report
Save your work as a Power BI report file (
.pbix).Use the template as a companion file and refer to the connector functions, this page, and the incremental refresh documentation for detailed explanations, parameters, and usage examples.
Utility functions
Convert timestamps from/to epoch
CDF resource types expect and return timestamps using milliseconds since the Unix epoch. Power Query doesn’t have methods to automatically parse this format to adatetimezone type to represent timezone-aware timestamps. CDF data models represent timestamps using the ISO 8601 format for primitive fields.
Use the functions below to convert between a datetimezone variable and milliseconds since the Unix epoch and from a datetimezone variable to text in ISO 8601 format.
ConvertMsToUtcDateTime returns a plain datetime that represents UTC, rather than a zone-aware value. Use it when the result is compared against the RangeStart and RangeEnd parameters used for incremental refresh. For the opposite direction, use ConvertDateTimeToMs.
ConvertDateTimeZoneToMs
ConvertDateTimeZoneToMs
Convert datetimezone to milliseconds since epoch
ConvertMsToDateTimeZone
ConvertMsToDateTimeZone
Convert milliseconds since epoch to datetimezone
ConvertMsToUtcDateTime
ConvertMsToUtcDateTime
Convert milliseconds since epoch to a UTC datetime
ConvertDateTimeZoneToIso
ConvertDateTimeZoneToIso
Convert DateTimeZone to ISO 8601 text representation
Add function
To add a new function in Power Query, select Get Data > Blank Query and write your function or copy one of the functions below.Time deltas
It’s common to define start and end timestamps based on time deltas. The values are updated when the semantic model is refreshed. In the example below,EndTime is the current time, and StartTime is 7 days before EndTime. The query returns a record with StartTime and EndTime in UTC. You can adapt it to use different time deltas.
Time deltas
Common GET request
When you fetch data from CDF using theGetCDF function from the CDF REST API connector for Power BI, you must use query parameters to pass on filters to select which data to fetch.
The example below shows how you can add the externalIdPrefix and limit query parameters from the /timeseries endpoint to the URL to filter data on the server side.
List all time series instances with an externalId starting with a specific string
Common POST request
When you fetch data from CDF with thePostCDF function, you must write a request body to select which data to fetch. The function accepts a text representation of the JSON body, but you can also write the body using a Power Query record data type and then convert it to a JSON text data type before passing the value to the PostCDF function.
List all data modeling instances for a view using the DMS API
") with another set of double-quote characters:
ListInstancesDMS, you can use it in a new query by entering the field values in Power Query or by writing a new query:
GraphQL requests
When you fetch data from CDF using theGraphQL function, you must write a GraphQL request to select which data to fetch from a specific data model. The function expects you to specify the external ID of the space, the external ID of the data model, the version of the data model, the GraphQL query to run, and optionally a set of variables to be used in the query.
The query below uses the GraphQL syntax and passes the variables as JSON texts. Using variables in the query makes it easier to parameterize and use with external values.
List all work orders with an end date greater than a specific date
#(lf) represents a line-break character. In the example above, the query was pasted into the text area field in Power BI and the variables were passed as JSON text. Notice how Power BI added the line breaks to the original query and expressed it as a single-line text variable.
Alternatively, you can write the query directly as a multi-line text variable. You can define the variables as Power Query records and convert them to JSON text before passing them to the GraphQL function. For example, see how the ConvertDateTimeZoneToIso function converts a datetimezone variable to a text representation of the ISO 8601 format and then passes it as a variable to the query.
Advanced examples
Depending on the shape of the Cognite API response, you may need additional Power Query transformations to fetch and transform the data. Copy and adapt the examples below to fit your business needs.Fetch sequence rows with the PostCDF function
The Power Query function below fetches and processes sequence rows data for a sequence external ID from CDF. It sends a POST request, extracts column information, expands nested response data, and reorganizes it into tabular format. The function handles data type conversion, removes unnecessary fields, and groups data by row. The final output is a well-structured table with correctly typed columns.
RetrieveSequenceRows function
RetrieveSequenceRows function
Fetch sequence rows with PostCDF
Fetch instances from the DMS query endpoint with the PostCDF function
The Power Query function below retrieves and processes data modeling instances for a DMS query. It paginates through the response, extracts the instances, and expands the nested data.
QueryDMS function
QueryDMS function
Fetch instances from the DMS query endpoint with PostCDF
Fetch time series datapoints with the PostCDF function
The Power Query function below retrieves and processes aggregated time series datapoints for a time series within a time range. It converts local timezone inputs to UTC for the CDF API requests, supports multiple aggregates and custom granularity, and handles data pagination. The function then converts the returned UTC timestamps back to the local timezone, expands the nested API response, and outputs a well-formatted table with properly typed columns. It also includes local timestamps and decimal aggregate values.
Use the optional fillLimit parameter to enable server-side gap filling for aggregate queries. The function sends fill = [limit = fillLimit] on the query item in every request, including subsequent pages.
RetrieveDataPoints function
RetrieveDataPoints function
Fetch time series datapoints with PostCDF
RetrieveDataPointsMultipleTs function
RetrieveDataPointsMultipleTs function
Fetch multiple time series datapoints with PostCDF
"4h" as the last parameter:
RetrieveDataPointsMultipleTs to iterate over a list of time series external IDs with daily aggregates and a two-day fill limit:
Fetch records from a stream with the PostCDF function
The Power Query function below fetches records through a record view. It reads the stream ID, property names, and data types from the view, then returns a table with a column for each selected property.
You can use this function with all stream types, including for incremental refresh. It selects records by lastUpdatedTime, the time CDF last created, updated, or deleted the record. For mutable streams, you also need to select the latest row for each record and keep deletion rows long enough to prevent older rows from reappearing. See Immutable and mutable streams before setting up refresh for a mutable stream.
Create the
PostCDF query from the connector and add ConvertMsToUtcDateTime from this page, plus ConvertDateTimeToMs and EnforceSchema from Utility functions.
RetrieveRecords function
RetrieveRecords function
Fetch records from a stream with PostCDF
usedFor is not record or that do not reference exactly one stream. An empty window (startUtc = endUtc) validates the view and returns the typed schema without reading records. A reversed window is an error.
To use the function:
RangeStart and RangeEnd to fetch each range, and include the row filter shown below so Power BI recognizes the date limits. This query works with either stream type. For mutable streams, also apply the latest-row and deletion handling described below.
Immutable and mutable streams
Both stream types can use incremental refresh. The difference is how you handle the rows after loading them:
A record is identified by its
space and externalId. In an immutable stream, keep all stored versions you need. Several versions can share the same space, externalId, and lastUpdatedTime, so deduplicating by those fields can discard valid records.
In a mutable stream, the same record identified by space and externalId can have several updates between refreshes with status created, updated, or deleted. A row with status = "deleted" is a deletion notice, also called a tombstone. It may still contain the record’s previous property values, so always check status to identify deleted records.
For smaller mutable streams, the simplest setup is a full refresh: reload all records still stored in CDF, then remove deleted rows:
Exclude deleted records
Keep deleted records out of incremental refresh results
With incremental refresh, Power BI reloads recent date ranges and keeps older ranges without reloading them. These ranges are called partitions. For example, you might keep one year of data but reload only the last seven days on each refresh. CDF returns deletion rows for at least three days after a record is deleted. Once loaded into Power BI, a deletion row stays there until Power BI replaces or removes its partition. If Power BI reloads that date range after CDF stops returning the deletion, the replacement partition no longer contains the deletion row. To use incremental refresh with a mutable stream, configure frequent refreshes so deletions load while CDF still returns them. Allow time for retries if a refresh fails. Because partitions can hold several rows for the same record, select the latest row for each record and exclude the deleted ones in the report. Add a calculated table that keeps only the row with the highestlastUpdatedTime per space and externalId, and drops records whose latest row is a deletion:
Keep the latest row for each record and exclude deletions
Size the initial load
The first refresh after publishing loads the entire period you chose to keep. Later refreshes reload only the recent period you configured. Each date range includes all records whoselastUpdatedTime falls within it. Check these two limits when planning the first load:
All reads from a stream share its download limit, even when Power BI loads several date ranges at once. To reduce download time, use the
properties parameter to select only the properties your report needs.
Estimate the payload as records × bytes per record. Measure representative responses with the properties you select. For an illustrative estimate, assume 900 bytes per record for a full view or 360 bytes for a subset. For a stream that ingests 7 million records a day:
- At 900 bytes per record, a day is about 6.3 GB. At an assumed effective throughput of 0.83 MB/s, that is about 2.1 hours per day, before model processing. Seven days takes about 15 hours and exceeds a standard refresh window.
- At 360 bytes per record, a day is about 2.5 GB and roughly 50 minutes at the same assumed throughput, before model processing.
RangeStart and RangeEnd a few minutes apart so the file stays small. The service builds the full history on the first refresh after you publish.
Backfill large histories outside Power BI
For streams with a large history, you can download older records to files first. Export a data dump of the records using the API, then set up incremental refresh only with recent data, combining all records into a single table in Power BI:Learn more: Microsoft Power Query documentation